
@ddd-ts-kit/knex
Knex adapters of the kernel and events ports: a unit of work that repositories never see, the
transactional outbox store, the processed-event store, a migration helper for their tables,
and one database schema per bounded context. Same pieces as @ddd-ts-kit/drizzle, for projects
that build their SQL with knex. Around them: the helpers of a repository (optimistic
concurrency, audit and tenant columns, pages), the four tenant isolation strategies, criteria
and read models, and the stores of the event store, the background jobs and the process
managers.
npm i @ddd-ts-kit/knex knex pgPostgreSQL first. MySQL 8 and SQLite work through the same code, see Dialect coverage for what is tested and how.
Where it sits in an application
Section titled “Where it sits in an application”Nothing here is imported from domain/ or application/. The domain declares its repository
ports and the application its query ports; the adapters written with this package live in the
infrastructure/ of each context, and the unit of work is built in platform/. One object is
the hinge: createKnexUnitOfWork(db) answers the UnitOfWork the command bus runs every
command in, and the KnexContext every adapter reaches the database through.
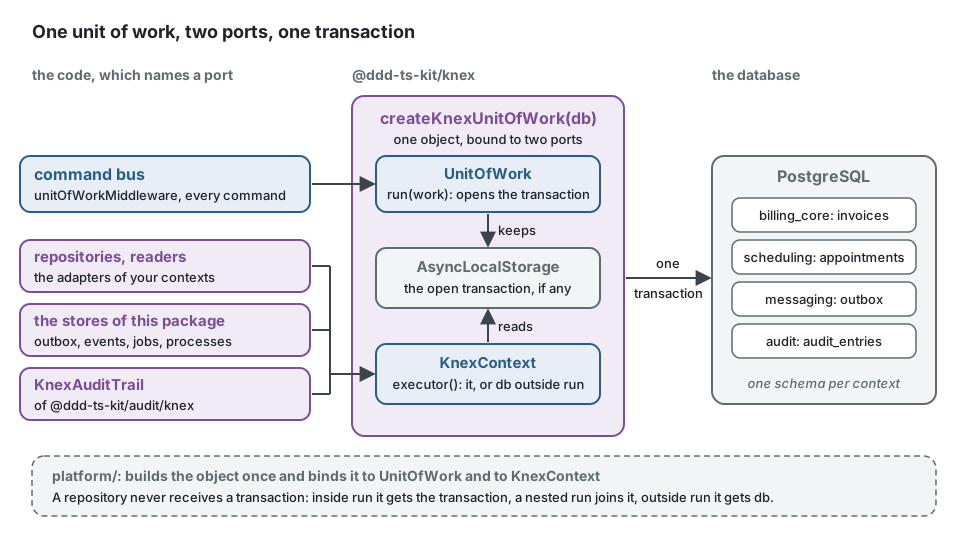
Instead of handing a transaction down the calls, which puts a knex type in every signature from the handler to the adapter and makes forgetting it a silent bug, the adapter asks the context where its statement runs:
import { knex, type Knex } from 'knex';import { createKnexUnitOfWork, KnexContext } from '@ddd-ts-kit/knex';
declare const config: { readonly databaseUrl: string };
interface InvoiceRow {  id: string;  status: 'draft' | 'issued';}
// Instead of `issue(id: string, transaction: Knex.Transaction)`, threaded from the handler:export class KnexInvoiceIssuer {  constructor(private readonly context: KnexContext) {}
  async issue(id: string): Promise<void> {    await invoicesOf(this.context).where({ id }).update({ status: 'issued' });  }}
function invoicesOf(context: KnexContext): Knex.QueryBuilder<InvoiceRow, InvoiceRow[]> {  return context.executor()<InvoiceRow, InvoiceRow[]>('invoices').withSchema('billing_core');}
const db = knex({ client: 'pg', connection: config.databaseUrl });const unitOfWork = createKnexUnitOfWork(db);const issuer = new KnexInvoiceIssuer(unitOfWork); // the unit of work is the KnexContext too
// Both updates run in the transaction `run` opened: they commit, or roll back, together.await unitOfWork.run(async () => {  await issuer.issue('inv-1');  await issuer.issue('inv-2');});
// Outside of `run`, `executor()` answers `db`: the update runs on its own.await issuer.issue('inv-3');
In an application the command bus calls run for you, and so do the consumers of
@ddd-ts-kit/di, so a handler never sees it; a script, or a consumer wired by hand, calls it
itself. With the CLI, init --orm knex writes this wiring, see
Composition root.
Tables
Section titled “Tables”The consuming project owns its migrations. createOutboxTables is a helper to call from one of
them:
import type { Knex } from 'knex';import { createOutboxTables, dropOutboxTables } from '@ddd-ts-kit/knex';
export const up = (knex: Knex) => createOutboxTables(knex, { schema: 'messaging' });export const down = (knex: Knex) => dropOutboxTables(knex, { schema: 'messaging' });
Without schema the tables live in the default schema of the connection. outboxTable and
processedEventsTable rename them. If you would rather not call a library from a migration,
this is the equivalent on PostgreSQL:
export async function up(knex: Knex): Promise<void> {  await knex.raw(`    create schema if not exists "messaging";
    create table "messaging"."outbox" (      "id" varchar(191) primary key,      "sequence" bigserial,      "type" text not null,      "version" integer not null,      "occurred_at" text not null,      "payload" jsonb,      "traceparent" text,      "correlation_id" text,      "status" varchar(16) not null default 'pending',      "attempts" integer not null default 0,      "next_attempt_at" timestamptz(3) not null,      "last_error_code" text,      "published_at" timestamptz(3),      "created_at" timestamptz(3) not null default current_timestamp(3)    );    create index "outbox_pending_idx" on "messaging"."outbox" ("next_attempt_at", "sequence")      where status = 'pending';
    create table "messaging"."processed_events" (      "consumer" varchar(191) not null,      "event_id" varchar(191) not null,      "processed_at" timestamptz(3) not null default current_timestamp(3),      primary key ("consumer", "event_id")    );  `);}
outbox is indexed for the relay (pending records by next attempt, partial index);
processed_events has (consumer, event_id) as its primary key. occurred_at is text on
purpose: the envelope comes back exactly as published, offset included.
A multi-tenant project keeps the tenant of each event, so that its consumers run in that tenant:
createOutboxTables(knex, { schema: 'messaging', tenant: true }) adds a nullable tenant_id
(addOutboxTenantColumn(knex, { schema: 'messaging', tenantOfUnpublished: 'acme' }) is the
migration of a project that becomes multi-tenant: the events not published yet go to the tenant
the database served, or keep none and are refused by tenant-scoped consumers if it is left out), and new KnexOutboxStore(context, { schema: 'messaging', tenant: true }) writes
it. A table that has the column is read back either way.
One schema per bounded context: schemaNameOf('order-management') gives order_management,
to pass to knex.schema.createSchemaIfNotExists, knex.schema.withSchema and
.withSchema(...) on queries. Contexts never join each other's tables.
Composition root
Section titled “Composition root”createKnexUnitOfWork(db) gives one object that is two ports: the kernel UnitOfWork, and
KnexContext, the handle repositories and stores run their queries on. Bind it to both:
import knex from 'knex';import { defineContextModule } from '@ddd-ts-kit/di';import { IntegrationEventPublisher, ProcessedEventStore, UnitOfWork } from '@ddd-ts-kit/kernel';import { OutboxPublisher, OutboxStore } from '@ddd-ts-kit/events';import {  createKnexUnitOfWork,  KnexContext,  KnexOutboxStore,  KnexProcessedEventStore,} from '@ddd-ts-kit/knex';
declare const config: { readonly databaseUrl: string }; // the configuration of the platform
const db = knex({ client: 'pg', connection: config.databaseUrl });const unitOfWork = createKnexUnitOfWork(db);
export const persistenceModule = defineContextModule({ name: 'persistence', register(builder) { builder.rebind(UnitOfWork).toValue(unitOfWork); builder.bind(KnexContext).toValue(unitOfWork); builder.bind(OutboxStore).toClass(KnexOutboxStore, [KnexContext]); builder.rebind(ProcessedEventStore).toClass(KnexProcessedEventStore, [KnexContext]); builder.rebind(IntegrationEventPublisher).toClass(OutboxPublisher, [OutboxStore]); },});const app = createApplication({ modules: [kernelModule(), persistenceModule, contextModule('billing', billingDeclarations)] });List the module after kernelModule(): rebind replaces its in-memory defaults. The command
bus of the kernel module runs every command in the bound UnitOfWork; handlers do not know it.
contextModule of @ddd-ts-kit/di turns the declared classes of a context into its module.
A project written by the CLI holds the same wiring in two files:
platform/database/persistence-over.ts builds the unit of work and its stores once, and
platform/platform.module.ts binds them, the outbox publisher being given to
kernelModule({ eventPublisher }).
toClass builds the stores with their default options (tables outbox and
processed_events in the default schema of the connection). A store with options is built by
a factory:
builder .bind(OutboxStore) .toFactory((resolve) => new KnexOutboxStore(resolve(KnexContext), { schema: 'messaging' }));builder .rebind(ProcessedEventStore) .toFactory((resolve) => new KnexProcessedEventStore(resolve(KnexContext), { schema: 'messaging' }));The relay reads the same store and hands the records to the broker:
const relay = new OutboxRelay({ store: app.resolve(OutboxStore), publisher: broker, clock: app.resolve(Clock) });relay.start({ intervalMs: 500 });unitOfWork.run(work) opens knex.transaction and keeps the transaction in an
AsyncLocalStorage; a nested run joins the outer transaction (no savepoint). Because
append uses the current transaction, an event published by a handler that then fails is
rolled back with the business write: that is the whole point of the outbox.
createKnexUnitOfWork(db, { isolationLevel: 'repeatable read' }) forwards the transaction
configuration of knex.
run is built on withinUnitOfWork of the kernel. The domain events of the aggregates saved
inside it wait until work has returned, then are dispatched inside the transaction, before
the commit: their handlers see every save, and what they write commits or rolls back with it.
If work, a handler or the commit fails, nothing is left: no row, no outbox record, no handler
run after the commit. Handlers declared after-commit run once the transaction has committed.
A nested run joins the unit of work in progress: one dispatch, at the end of the outermost.
A run called directly (a consumer, a script) has the same timing as a command.
unitOfWorkContract of @ddd-ts-kit/testing/contracts proves it, with a deferred constraint
for the commit that fails; on a real PostgreSQL (DDD_TS_KIT_TEST_DATABASE_URL) it also proves
that the rows of a before-commit handler are invisible from another connection and visible
to the after-commit handlers.
KnexContext is an abstract class, so it is its own injection token. A project with two
databases gives each a class of its own (export abstract class Ledger extends KnexContext {}
in platform/database/) and binds each to its unit of work.
Repository
Section titled “Repository”The port lives in the domain, the adapter in infrastructure. A repository receives the context,
never a transaction: executor() is the transaction of the unit of work when there is one and
the root knex instance otherwise.
import { Repository } from '@ddd-ts-kit/kernel';
export abstract class InvoiceRepository extends Repository<Invoice> {}import type { Knex } from 'knex';import { AggregateRoot } from '@ddd-ts-kit/kernel';import { Repository } from '@ddd-ts-kit/kernel/declarations';import { insertIgnoringConflict, KnexContext, optimisticUpdate, schemaNameOf } from '@ddd-ts-kit/knex';
const BILLING = schemaNameOf('billing-core'); // billing_core
interface InvoiceRow { id: string; amount: number; status: 'draft' | 'issued'; version: number;}
// What the domain of the context holds, declared so that this file reads alone.type InvoiceState = Omit<InvoiceRow, 'version'>;
declare class Invoice extends AggregateRoot { static rehydrate(state: InvoiceState): Invoice; readonly state: InvoiceState;}
declare abstract class InvoiceRepository { abstract findById(id: string): Promise<Invoice | undefined>; abstract save(invoice: Invoice): Promise<void>;}
@Repository(InvoiceRepository)export class KnexInvoiceRepository implements InvoiceRepository { constructor(private readonly context: KnexContext) {}
async findById(id: string): Promise<Invoice | undefined> { const row = await invoicesOf(this.context).where({ id }).first();
if (row === undefined) { return undefined; }
const invoice = Invoice.rehydrate(row); invoice.version = row.version;
return invoice; }
async save(invoice: Invoice): Promise<void> { await optimisticUpdate(invoice, async ({ expected, next }) => { const row = { ...invoice.state, version: next };
if (expected === 0) { const inserted = await insertIgnoringConflict(this.context.executor(), invoicesOf(this.context), { row, conflict: 'id' });
return inserted ? 1 : 0; }
return invoicesOf(this.context).where({ id: invoice.id, version: expected }).update(row); }); }}
// A function, not a method: see below.function invoicesOf(context: KnexContext): Knex.QueryBuilder<InvoiceRow, InvoiceRow[]> { return context.executor()<InvoiceRow, InvoiceRow[]>('invoices').withSchema(BILLING);}No method of an adapter answers a query builder. A knex builder is thenable, and what
wraps an adapter from outside (the spans of @ddd-ts-kit/tracing, an aspect) reads a method
that answered a thenable as asynchronous: from its second call the method answers a promise
of the rows, and .where(...) on it fails. The table is therefore reached through a function
of the module, as the repository the CLI generates does, and a private method that runs a
statement is declared async:
import type { Knex } from 'knex';import { KnexContext } from '@ddd-ts-kit/knex';
interface InvoiceRow {  id: string;  amount: number;}
// Instead of a method that answers the builder: once a span wraps the adapter, the second call// of `invoices()` answers a promise of the rows, and `.where(...)` on it throws.export class FragileInvoiceTotals {  constructor(private readonly context: KnexContext) {}
  async totalOf(id: string): Promise<number | undefined> {    return (await this.invoices().where({ id }).first())?.amount;  }
  private invoices(): Knex.QueryBuilder<InvoiceRow, InvoiceRow[]> {    return this.context.executor()<InvoiceRow, InvoiceRow[]>('invoices');  }}
// Write: the table is reached through a function of the module, and every method is async.export class KnexInvoiceTotals {  constructor(private readonly context: KnexContext) {}
  async totalOf(id: string): Promise<number | undefined> {    return (await invoicesOf(this.context).where({ id }).first())?.amount;  }}
function invoicesOf(context: KnexContext): Knex.QueryBuilder<InvoiceRow, InvoiceRow[]> {  return context.executor()<InvoiceRow, InvoiceRow[]>('invoices');}
In the explicit style, without the decorator, the same binding is one line of
<context>.module.ts:
builder.bind(InvoiceRepository).toClass(KnexInvoiceRepository, [KnexContext]).
optimisticUpdate gives the version to expect and the version to write, raises a
ConcurrencyError (a DomainError with code CONCURRENCY_CONFLICT) when the guarded
statement wrote no row, and moves invoice.version on otherwise. insertIgnoringConflict
inserts unless the key exists and says whether it did; unlike a caught unique violation it
leaves the surrounding PostgreSQL transaction usable, and it hides the one place where the
dialects differ (RETURNING on PostgreSQL and SQLite, the affected-row count on MySQL).
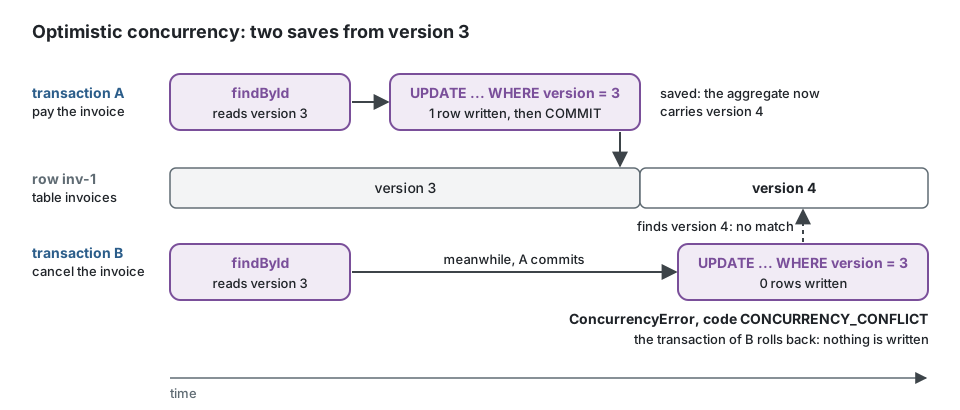
The second writer is refused instead of silently overwriting the first. Nothing retries it for
you: the caller receives the ConcurrencyError and decides whether to load the invoice again.
Audit columns, tenant scoping and pages
Section titled “Audit columns, tenant scoping and pages”The standard persistence shapes of the kernel, on knex. Four small helpers, so that the columns
have the same names in every project (created_at, created_by, updated_at, updated_by,
tenant_id), which is what lets a dashboard, an export or the audit package be written once:
auditColumns(table) and tenantColumn(table) for the migration, auditRow(stamp) and
tenantRow(scoped) to turn the kernel AuditStamp and TenantScoped into those column names,
since a knex row is keyed by column.
import { auditColumns, tenantColumn } from '@ddd-ts-kit/knex';
export async function up(knex: Knex): Promise<void> {  await knex.schema.withSchema(BILLING).createTable('invoices', (table) => {    table.text('id').primary();    table.integer('amount').notNullable();    table.text('status').notNullable();    table.integer('version').notNullable();    tenantColumn(table);    auditColumns(table);    table.index(['tenant_id', 'amount', 'id'], 'invoices_tenant_amount_idx');  });}
import { Clock, ExecutionScope, stampCreation, stampUpdate, tenantScopeOf } from '@ddd-ts-kit/kernel';import { auditRow, tenantRow, type AuditRow, type TenantRow } from '@ddd-ts-kit/knex';
interface InvoiceRow extends VersionedInvoice, TenantRow, AuditRow {}
@Repository(InvoiceRepository)export class KnexInvoiceRepository implements InvoiceRepository { constructor( private readonly context: KnexContext, private readonly scope: ExecutionScope, private readonly clock: Clock, ) {}
async findById(id: string): Promise<Invoice | undefined> { const row = await invoicesOf(this.context).where({ id, ...this.ownTenant() }).first();
return row === undefined ? undefined : InvoiceMapper.toDomain(row); }
async save(invoice: Invoice): Promise<void> { await optimisticUpdate(invoice, async ({ expected, next }) => { const state = { ...InvoiceMapper.toRow(invoice), version: next };
return expected === 0 ? this.insert(state) : this.update(state, expected); }); }
private async insert(state: VersionedInvoice): Promise<number> { const row = { ...state, ...this.ownTenant(), ...auditRow(stampCreation(this.scope, this.clock)) }; const inserted = await insertIgnoringConflict(this.context.executor(), invoicesOf(this.context), { row, conflict: 'id' });
return inserted ? 1 : 0; }
private async update(state: VersionedInvoice, expected: number): Promise<number> { return invoicesOf(this.context) .where({ id: state.id, version: expected, ...this.ownTenant() }) .update({ ...state, ...auditRow(stampUpdate(this.scope, this.clock)) }); }
private ownTenant(): TenantRow { return tenantRow(tenantScopeOf(this.scope)); }}A search query takes the kernel PageRequest and answers a Page, in both variants:
export abstract class InvoiceQueries { abstract search(request: PageRequest<'amount'>): Promise<Page<InvoiceSummary>>;}import { ExecutionScope, encodeCursor, pageOf, tenantScopeOf } from '@ddd-ts-kit/kernel';import { Repository } from '@ddd-ts-kit/kernel/declarations';
@Repository(InvoiceQueries)export class KnexInvoiceQueries implements InvoiceQueries { constructor( private readonly context: KnexContext, private readonly scope: ExecutionScope, ) {}
async search(request: PageRequest<'amount'>): Promise<Page<InvoiceSummary>> { return request.kind === 'offset' ? this.byOffset(request) : this.byCursor(request); }
private async byOffset(request: OffsetPageRequest<'amount'>): Promise<Page<InvoiceSummary>> { const rows = await ownInvoices(this.context, this.scope) .orderBy(totalOrder(directionOf(request))) .limit(request.limit) .offset(request.offset); const counted = await ownInvoices(this.context, this.scope).count<{ total: string | number }[]>({ total: '*' }).first();
return pageOf(rows.map(toSummary), { total: Number(counted?.total ?? 0) }); }
private async byCursor(request: CursorPageRequest<'amount'>): Promise<Page<InvoiceSummary>> { const direction = directionOf(request); const query = ownInvoices(this.context, this.scope).orderBy(totalOrder(direction)).limit(request.limit + 1); const rows = await (request.cursor === undefined ? query : beyond(query, positionOf(request.cursor), direction)); const items = rows.slice(0, request.limit); const last = items.at(-1); const more = rows.length > request.limit && last !== undefined;
return pageOf(items.map(toSummary), more ? { nextCursor: encodeCursor({ amount: last.amount, id: last.id }) } : {}); }}
function ownInvoices(context: KnexContext, scope: ExecutionScope) { return invoicesOf(context).where(tenantRow(tenantScopeOf(scope)));}
const directionOf = (request: PageRequest<'amount'>) => request.sort[0]?.direction ?? 'asc';
// The primary key follows the sort field, in the same direction: the order is total.const totalOrder = (direction: SortDirection) => [ { column: 'amount', order: direction }, { column: 'id', order: direction },];
// The rows after a position, as a tuple comparison: the tie-breaker decides among equals.function beyond(query: Knex.QueryBuilder, { amount, id }: { amount: number; id: string }, direction: SortDirection) { const past = direction === 'asc' ? '>' : '<';
return query.where((after) => { void after.where('amount', past, amount).orWhere((tied) => { void tied.where('amount', amount).where('id', past, id); }); });}positionOf(cursor) decodes with decodeCursor and checks that amount is a number and id
a string, raising InvalidPageRequestError otherwise.
A read adapter over the database is declared with @Repository, as the ones the CLI
generates: its kind is repository. Declared with @Adapter it would be external, and a
generated platform puts a retry and a time limit around every external and gateway
adapter, which a statement of the unit of work must not get.
The rules these examples hold, and that the tests of this package check on a real database:
- Audit columns are filled by the adapter, never by the aggregate:
stampCreation(scope, clock)on insert,stampUpdate(scope, clock)on update, which leavescreated_atandcreated_byalone. The actor is the one of the execution scope: the user of the request, orsystem:<consumer>for a consumed event. - The tenant is part of every statement: written on insert, and in the condition of every
read and every update, the version guard included. A row of another tenant is not found, and
an update aimed at it writes nothing, which
optimisticUpdatereports as aConcurrencyError. Work that names no tenant raisesNoCurrentTenantErrorbefore any SQL. - A list has a total order. The primary key follows the sort field, in the same direction,
as a tie-breaker: rows equal on the sort field otherwise have no defined order, and a page
could repeat or skip one of them. The index covers
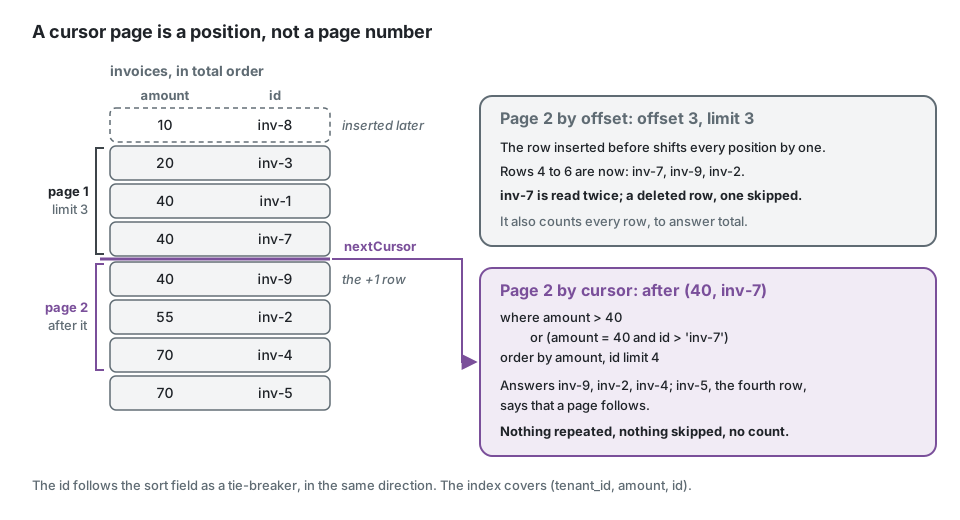
(tenant_id, <sort field>, id). - A cursor is a position, not a page number: the sort value and the id of the last row,
written by
encodeCursor, compared as a tuple (`amount > :amount OR (amount = :amount AND id:id)
). One row more thanlimitis fetched to know whether a page follows, so no count is needed, and a row inserted before the cursor does not shift the next page as it does with an offset. A cursor comes back from a client:decodeCursor` refuses what it did not write, and the adapter checks the types of the position before they reach a statement. - An offset page answers
total, a cursor pagenextCursor. Offer the offset form for small, browsable lists and the cursor form for anything that grows.
What the cursor buys, on invoices sorted by amount, when a row is inserted between two pages:
Tenant isolation
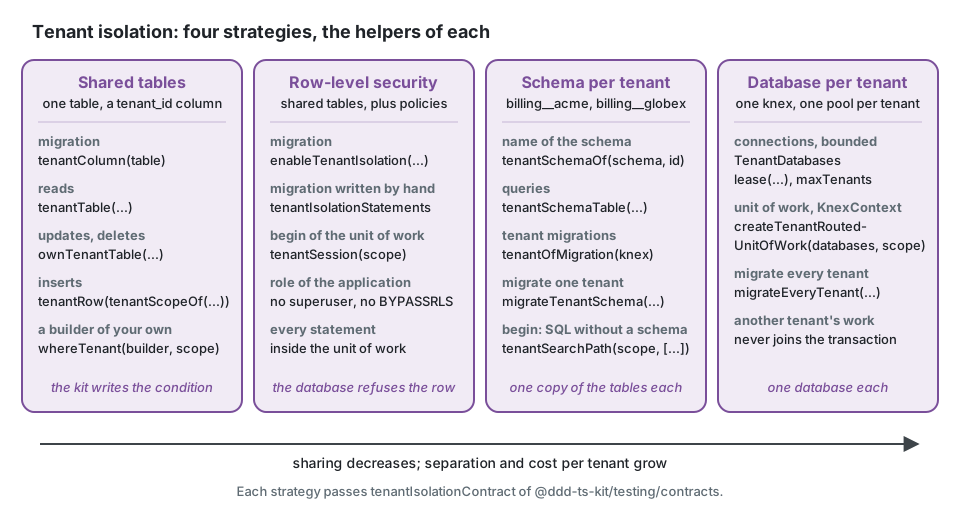
Section titled “Tenant isolation”Four strategies, chosen per project (Multitenancy says
when each fits). Every one of them is proven here by tenantIsolationContract of
@ddd-ts-kit/testing/contracts, on PGlite and on PostgreSQL.
Shared tables. One table per aggregate, a tenant_id column, and every statement confined
by the kit instead of by a condition written by hand:
const INVOICES = { schema: BILLING, table: 'invoices' };
// reads: the tenant of the work, or the tenants of an elevationconst row = await tenantTable<InvoiceRow>(this.context, this.scope, INVOICES).where({ id }).first();// updates and deletes: the one tenant of the work, which an elevation never widensawait ownTenantTable<InvoiceRow>(this.context, this.scope, INVOICES).where({ id, version: expected }).update(changes);// inserts name the tenant themselvesconst inserted = { ...state, ...tenantRow(tenantScopeOf(this.scope)), ...auditRow(stampCreation(this.scope, this.clock)) };
whereTenant(builder, scope) is the condition alone, for a builder of your own. Work that names
no tenant raises NoCurrentTenantError before any SQL. A read model of tenant data passes
tenant: scope to KnexReadModelTable and KnexReadModelStore: each row is written with the
tenant of the work and every read and write is confined to it (keys stay unique across tenants;
a rebuild, which runs in no tenant, is refused).
A measure grouped by a scoped query, then filtered, sorted and paged by its output columns,
selects from it with derivedTable(context, grouped, 'occupancy'): the grouped query is the one
that reaches the table, through tenantTable. A project of one customer that becomes
multi-tenant adds the column to each table of tenant data in a migration,
addTenantColumn(knex, { schema, table, tenantOfExistingRows: 'acme' }): the rows already there
go to that tenant (refused when there are rows and no tenant), then the column is required and
indexed; a table that already has it is left alone.
Row-level security, a second line on shared tables: the database itself refuses a row of another tenant, even to a statement that forgot its condition.
// the migration that creates the tableawait enableTenantIsolation(knex, INVOICES); // enable, force on the owner, one policy per command
// the composition rootconst unitOfWork = createKnexUnitOfWork(knex, undefined, { begin: tenantSession(executionScope) });
tenantSession sets the tenant settings for each transaction only (set_config(..., true)), so
a pooled connection never carries a tenant into the next one: ddd_ts_kit.tenant_id, and for an
elevation ddd_ts_kit.reach (the tenants listed) or ddd_ts_kit.every_tenant. There is one
policy per command: a select sees the tenant of the work and what an elevation reaches; an
insert, an update and a delete only ever touch the tenant of the work, so an elevated
delete from invoices without a condition removes no other tenant's row.
tenantIsolationStatements(target) gives the SQL for a migration written by hand. Three
conditions hold it: the application connects with a role that is not a superuser and has no
BYPASSRLS (both ignore every policy); every statement runs inside the unit of work (a
statement outside of a transaction carries no setting and sees nothing, so queries go through the
unit of work too); migrations run as the owner, outside of it.
Schema per tenant. The tables of a context exist once per tenant, in <schema>__<tenant>
(tenantSchemaOf('billing', 'acme'); a tenant id that a schema name could not hold as it is, is
refused rather than altered). tenantSchemaTable(context, scope, { schema: BILLING, table: 'invoices' }) reaches the tenant's copy. The tenant migrations live in a directory of their own
and name their schema from the tenant they run for:
export async function up(knex: Knex): Promise<void> {  const schema = tenantSchemaOf(BILLING, tenantOfMigration(knex));
  await knex.schema.createSchemaIfNotExists(schema);  await knex.schema.withSchema(schema).createTable('invoices', (table) => { /* ... */ });}
migrateTenantSchema(knex, tenantId, { directory: 'migrations/tenant' }) applies them for one
tenant and records them in migrations__<tenant>, so each tenant moves on its own and a new
tenant is provisioned by its first run. tenantSearchPath(scope, [BILLING]) is a begin that
sets the search path of each transaction to the tenant's schemas only, for SQL that names no
schema. An elevation does not reach several schemas at once: staff read one tenant at a time.
Database per tenant. new TenantDatabases({ connectionOf: (tenantId) => configOf(tenantId), maxTenants: 20 }) opens one knex (one bounded pool) per tenant on first use. At most
maxTenants instances exist at once, those still closing included, so the server never has to
accept more than maxTenants * pool.max connections per instance of the application. Work holds
the instance of its tenant by a lease (databases.lease(tenantId, (knex) => ...)): an instance is
closed only when no work holds it, the least recently used first, and work for another tenant
waits for a place instead of opening beyond the bound. createTenantRoutedUnitOfWork(databases, scope) is the unit of work and KnexContext: each transaction holds a lease on the database of
the tenant of the work until it ends; every statement runs inside it
(StatementOutsideUnitOfWorkError otherwise, so queries go through the unit of work too), work
that names no tenant reaches no database, and work of another tenant never joins an open
transaction (CrossTenantUnitOfWorkError). migrateEveryTenant(databases, directory, migrate)
applies the migrations to every tenant of a TenantDirectory, stopping at the first failure and
naming its tenant.
Criteria
Section titled “Criteria”criteriaToKnex(builder, plan, columns) adds a criteria plan of the kernel to a query: the
filters and the scope of the actor, the keyset of a cursor page, the total order ended by the
tie-breaker, the window. predicateToKnex(builder, predicate, columns) adds the filters alone,
for a count. columns maps each field of the read model to its column, and is the only source
of identifiers: every value is a binding, a text search is like ? escape ? with %, _ and
\ escaped.
async search(criteria: ScopedCriteria<AppointmentRow>): Promise<Page<AppointmentRow>> {  const plan = planCriteria(appointmentCriteria, criteria);
  if (plan.empty) {    return pageOfPlan(plan, []);  }
  const rows = await criteriaToKnex(this.context.executor()<AppointmentRow>('appointment_list'), plan, COLUMNS);
  return pageOfPlan(plan, rows.map(toRow));}
A cursor page is fetched one row longer than asked, which is how pageOfPlan knows whether
another follows; an offset page takes its total from a second statement
(predicateToKnex(...).count()). A field declared nullable is ordered nulls last
ascending and nulls first descending on every dialect.
Strings. A text column is ordered and compared by range in the collation of the column;
criteria order strings by code point. Declare the text columns that are sorted or compared
with gt, lt or between with COLLATE "C": the index then serves the sort, and the
order is the same as in the fake. Decimals are a numeric column and a string in the
row; they read back in the scale of the column. Instants are timestamptz and a Date.
An integer is integer: a bigint comes back as a string from the driver.
Read models
Section titled “Read models”// the migrationawait knex.schema.withSchema('scheduling').createTable('appointment_list', (table) => { table.text('id').primary(); table.text('status').notNullable(); table.datetime('starts_at', { useTz: true, precision: 3 }).notNullable(); readModelColumns(table); // last_event_id, last_event_at, last_event_version, deleted});
// infrastructure/persistence/knex-appointment-list.repository.ts@Repository(AppointmentList)export class KnexAppointmentList extends KnexReadModelStore<AppointmentRow> implements AppointmentList { constructor(context: KnexContext) { super(context, { schema: 'scheduling', table: 'appointment_list', columns: { id: 'id', status: 'status', startsAt: 'starts_at' }, definition: appointmentCriteria, }); }}Every write goes through TableReadModelStore of the kernel: a row is written only if its
event is newer than the one it holds, on the executor of the unit of work, so the row and the
processed-event mark commit together. A removed row stays in the table with deleted set:
a query of your own on the table leaves those rows out, and so does a unique index
(WHERE NOT deleted). store.table is what ProjectionRebuild takes; the rebuild is
PostgreSQL only (a copy <table>__rebuild made LIKE ... INCLUDING ALL, the keys written
meanwhile in <table>__touched, the swap by rename in one transaction) and its guarantees
and limits are in the README of @ddd-ts-kit/kernel ("Rebuild"). The store passes
criteriaContract and readModelStoreContract of @ddd-ts-kit/testing/contracts, on PGlite
and on PostgreSQL 18.
Criteria and read models were never run on MySQL or SQLite.
Outbox and idempotency
Section titled “Outbox and idempotency”KnexOutboxStore.claimBatchselects the due rowsFOR UPDATE SKIP LOCKEDand leases them in the same short transaction by pushingnext_attempt_atforward (leaseMs, default 30 s), so several relays share the work without waiting for each other, and the records of a relay that died come back when the lease expires. Delivery is at least once, unordered.- Where the database has no
SKIP LOCKED(SQLite), or when you passclaim: 'compare-and-set', the claim reads the due rows and takes each one with an update guarded by the attempt count it read: same guarantee, no lock clause, one statement per record. The default isskip-lockedon PostgreSQL and MySQL,compare-and-setelsewhere. KnexProcessedEventStore.markProcessedis an insert ignoring the conflict on(consumer, event_id). Run the consumer inside the unit of work: the mark then commits with the effects of the handler, and disappears with them if it fails.
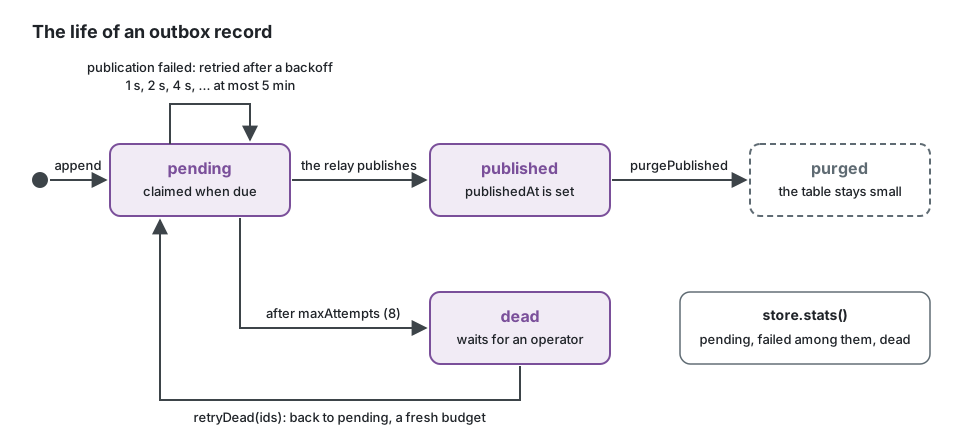
The life of one record in the outbox table. The relay of @ddd-ts-kit/events drives it through
claimBatch, markPublished and markFailed; retryDead, purgePublished and stats are
called by an operator or a scheduled job, never by the relay:
Event store
Section titled “Event store”// a migration of the projectexport const up = (knex) => createEventStoreTables(knex, { schema: 'scheduling' });
// the composition rootconst { events, snapshots, checkpoints, subjectKeys } = createKnexEventSourcing(unitOfWork, { schema: 'scheduling' });createEventStoreTables runs eventStoreTablesSql of the kernel: stored_events,
stored_events_head, stream_snapshots, subscription_checkpoints and subject_keys, in the
schema of the context. createKnexEventSourcing refuses a knex that does not speak PostgreSQL.
Each statement runs on the executor of the context: an append joins the transaction of the
unit of work, so the stream and the outbox records its events publish commit together
(eventStoreUnitOfWorkContract). Appends take the head of the store, a row locked until their
transaction ends: positions are given in commit order, without gaps, and two appends never run
side by side, whatever their streams. PostgreSQL only. The stores are the ones of the kernel
(PostgresEventStore and its companions), held to eventStoreContract here; how an
event-sourced aggregate uses them: the README of @ddd-ts-kit/kernel, section "Event sourcing".
Background jobs
Section titled “Background jobs”KnexJobStore is the JobStore of @ddd-ts-kit/scheduling on PostgreSQL: the background jobs
of a context in a table of its schema, createJobTable(knex, { schema }) called from a
migration. add runs on the executor of the context, so a job enqueued by a command is written
by the transaction of the command; claims select the due rows FOR UPDATE SKIP LOCKED in a
short transaction of their own and lease them. Bind it in the composition root:
kernelModule({ unitOfWork, jobStore: new KnexJobStore(unitOfWork, { schema: 'scheduling' }) });export const up = (knex) => createJobTable(knex, { schema: 'scheduling' });export const down = (knex) => dropJobTable(knex, { schema: 'scheduling' });The store passes jobStoreContract, its unit of work suite included, on PGlite and on
PostgreSQL. MySQL and SQLite are not covered: the table uses jsonb and a partial index.
What the jobs guarantee: Background jobs.
Process managers
Section titled “Process managers”KnexProcessStore is the ProcessStore of the kernel: one row per process and correlation key
in process_instances, created by createProcessTable(knex, { schema }) from a migration
(dropProcessTable is its down). A first save inserts, ignoring a row a concurrent first save
wrote; a next one updates the row at the previous version; a save that changes no row throws
ConcurrencyError. It runs on the executor of the context, in the transaction of the step, and
passes processStoreContract with its unit of work.
Dialect coverage
Section titled “Dialect coverage”What follows is about this package. The CLI generates for PostgreSQL only: init --orm knex
refuses --database mysql and --database sqlite.
| Database | Status |
|---|---|
| PostgreSQL | Covered by the automated suite: contract suites of @ddd-ts-kit/testing, repository contract, rollback, nested unit of work, concurrent claims. It runs on PGlite served over the PostgreSQL wire protocol by default, and on a real server when DDD_TS_KIT_TEST_DATABASE_URL is set (last run: PostgreSQL 18). |
| MySQL 8 | Not in the automated suite. The outbox and processed-event contract suites and the rollback of append were run once by hand against MySQL 8.4 with mysql2, with skip-locked and compare-and-set. |
| SQLite | Not in the automated suite. The same suites were run once by hand with better-sqlite3. No SKIP LOCKED: the claim is compare-and-set. No schemas: createOutboxTables refuses schema, name the tables per context instead. |
| MariaDB, CockroachDB, SQL Server, Oracle | Never run. MariaDB stores JSON as text, so the payload would come back as a string. |
Limits
Section titled “Limits”- MySQL
DATETIMEhas no time zone and knex converts dates in the time zone of the process: give every process the same one, or settimezone: 'Z'on the connection. - On MySQL 5.7 and MariaDB before 10.6 there is no
SKIP LOCKED: passclaim: 'compare-and-set'. - The outbox payload is serialized with
JSON.stringify, so it must be JSON, which the integration event contract already requires. Anundefinedpayload is stored as SQLNULLand read back asnull. - Ordering is not guaranteed, not even per aggregate: a failed event is retried later while its successors go out.
Testing an adapter
Section titled “Testing an adapter”The unit of work of this package passes unitOfWorkContract, and its stores
outboxStoreContract and processedEventStoreContract, of @ddd-ts-kit/testing/contracts.
Hold your repositories to repositoryContract the same way, next to their in-memory fake: the
same suite then proves that the fake the handlers are tested with behaves as the adapter that
runs in production (found after a save, kept apart, later saves stored, unsaved changes ignored,
an unseen change refused with CONCURRENCY_CONFLICT).
import { afterAll, afterEach, beforeEach, describe, expect, it } from 'vitest';import { knex } from 'knex';import { AggregateRoot } from '@ddd-ts-kit/kernel';import { createKnexUnitOfWork, KnexContext } from '@ddd-ts-kit/knex';import { repositoryContract } from '@ddd-ts-kit/testing/contracts';
// The aggregate and the adapter of the context, declared so that this file reads alone.declare class Invoice extends AggregateRoot {  static draft(id: string, amount: number): Invoice;  addCharge(amount: number): void;  readonly state: { readonly amount: number; readonly status: 'draft' | 'issued' };}
declare class KnexInvoiceRepository {  constructor(context: KnexContext);  findById(id: string): Promise<Invoice | undefined>;  save(invoice: Invoice): Promise<void>;}
declare const testDatabaseUrl: string; // a database of the test run, migrated
const db = knex({ client: 'pg', connection: testDatabaseUrl });let next = 0;
afterAll(() => db.destroy());
repositoryContract<Invoice>(  { describe, it, expect, beforeEach, afterEach },  {    name: 'KnexInvoiceRepository',    createRepository: async () => {      await db('invoices').withSchema('billing_core').delete();
      return new KnexInvoiceRepository(createKnexUnitOfWork(db));    },    createAggregate: () => Invoice.draft(`inv-${(next += 1)}`, 100),    mutate: (invoice) => invoice.addCharge(50),    idOf: (invoice) => invoice.id,    stateOf: (invoice) => invoice.state,  },);
The tests of this package need no container:
npx vitest run packages/knexDDD_TS_KIT_TEST_DATABASE_URL=postgresql://user:password@localhost:5432/postgres npx vitest run packages/knexWith the variable set, each spec file creates a database of its own on that server and drops it afterwards, and the tests that need two real connections (a relay passing over rows locked by another one) run instead of being skipped.